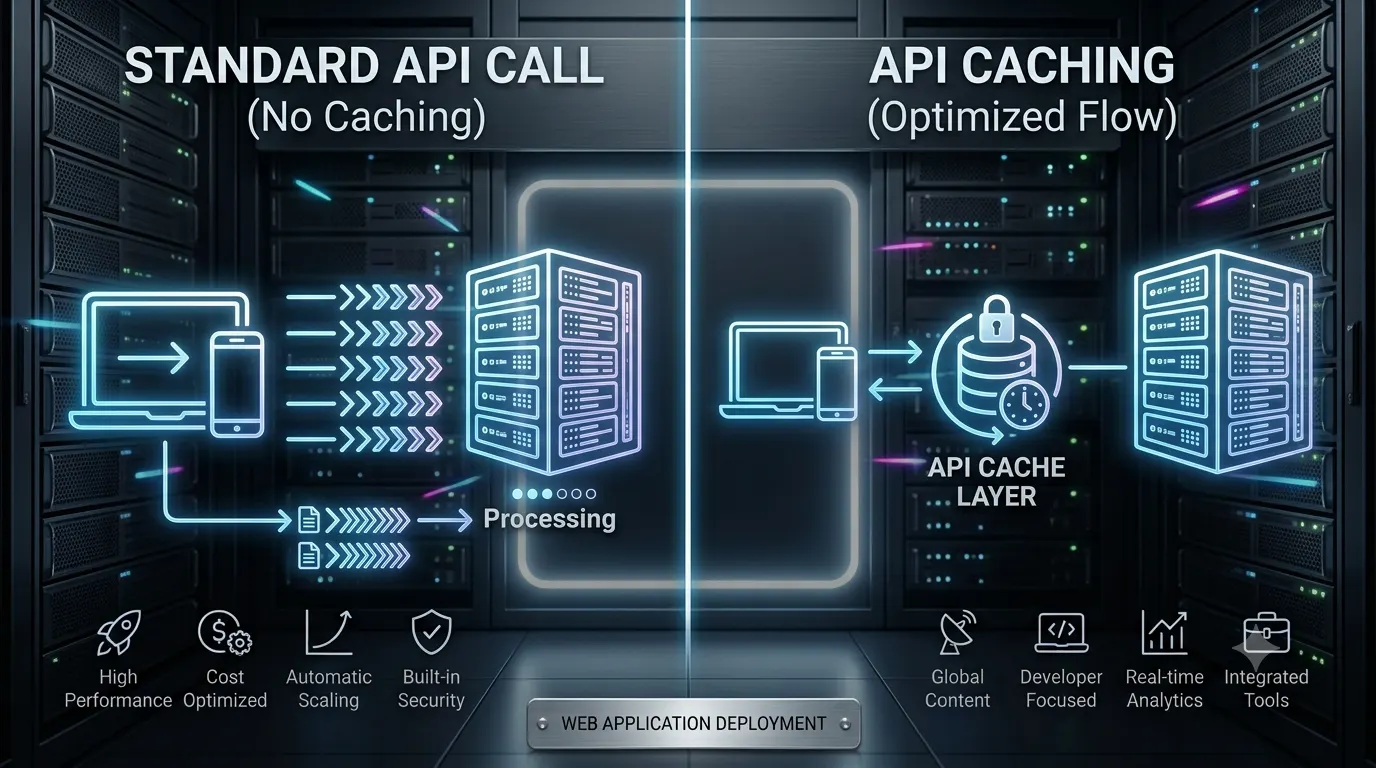
Modern applications depend heavily on APIs. Whether you’re building a web application, mobile app, SaaS platform, e-commerce website, or backend system, APIs are often responsible for retrieving and delivering data.
As the number of users and API requests increases, repeatedly fetching the same data from a database or external service can become expensive and slow.
This is where API caching becomes useful.
API caching stores frequently requested API responses temporarily so that future requests can be served faster without repeatedly performing the same backend operations.
In this guide, we’ll explain what API caching is, how it works, different caching strategies, common cache locations, benefits, limitations, and API caching best practices.
What Is API Caching?
API caching is the process of temporarily storing API responses so that subsequent requests for the same data can be served from the cache instead of processing the request from the beginning.
Without caching, a typical API request might look like this:
Client → API → Backend → Database → Backend → API → Client
If the same data is requested repeatedly, the backend may query the database again and again.
With caching, the flow can become:
Client → API → Cache → Response
If the requested data already exists in the cache, the application can return it without querying the database.
This can significantly reduce response time and backend workload.
Why Is API Caching Important?
Imagine an application with 100,000 users.
Suppose thousands of users request the same information, such as:
- Product categories
- Public configuration
- Popular products
- Country lists
- Blog posts
- Exchange rates
- Dashboard statistics
- Public profiles
- Frequently accessed API responses
If every request reaches the database, the application may perform thousands of unnecessary database operations.
Caching allows the application to reuse previously generated responses.
This can provide several benefits:
- Faster API responses
- Lower database load
- Reduced server workload
- Better application scalability
- Lower infrastructure costs
- Improved user experience
How Does API Caching Work?
A simple caching process usually follows these steps.
Step 1: Client Sends a Request
A client requests an API endpoint.
For example:
GET /api/products
Step 2: Application Checks the Cache
The backend checks whether a cached response for that request already exists.
Step 3: Cache Hit
If the response exists and hasn’t expired, the API returns the cached data.
This is called a cache hit.
Step 4: Cache Miss
If the data isn’t available in the cache, the backend retrieves the information from the database or another service.
This is called a cache miss.
Step 5: Store the Response
The backend stores the response in the cache for a specified amount of time.
Step 6: Return the Response
The API sends the response to the client.
Future requests can then use the cached version.
Cache Hit vs Cache Miss
Two important concepts in caching are cache hit and cache miss.
Cache Hit
A cache hit happens when the requested data is already available in the cache.
Example:
A user requests:
GET /api/products
The cache already contains the response.
The API returns the cached response immediately.
Cache Miss
A cache miss occurs when the requested data isn’t available in the cache.
The backend must retrieve the data from its original source.
For example:
Client → API → Cache → Database
After retrieving the data, the application can store it in the cache for future requests.
A high cache-hit rate generally means the caching strategy is working effectively.
Where Can API Caching Be Implemented?
Caching doesn’t have to happen in only one place.
Different layers of an application can cache API responses.
1. Browser Cache
Web browsers can cache certain HTTP responses.
For example, static resources and cacheable API responses may be stored locally.
This can reduce network requests and improve page performance.
However, browser caching should be configured carefully when data changes frequently.
2. CDN Cache
A Content Delivery Network, or CDN, can cache responses at edge locations closer to users.
Instead of every request traveling to the main application server, cached content can sometimes be delivered from an edge location.
This is especially useful for:
- Public APIs
- Static content
- Images
- Videos
- Public pages
- Frequently requested resources
3. Reverse Proxy Cache
A reverse proxy can sit between clients and your application servers.
It can cache API responses and serve repeated requests without forwarding every request to the backend.
This can reduce application-server workload.
4. Application-Level Cache
The backend application itself can maintain cached data.
For example, a Node.js application might check a cache before querying a database.
A common architecture is:
Client → API → Application → Redis → Database
If the data exists in Redis, the application can return it directly.
If it doesn’t, the application queries the database and stores the result in Redis.
5. Distributed Cache
For applications running across multiple servers, a distributed cache can be useful.
Common technologies include:
- Redis
- Memcached
A distributed cache allows multiple application instances to access shared cached data.
This becomes particularly useful when an application scales horizontally.
What Is TTL in API Caching?
TTL stands for Time To Live.
It determines how long cached data should remain valid.
For example, suppose an API caches product data for 10 minutes.
The TTL is:
600 seconds
After the TTL expires, the cached data can be considered stale and the application may retrieve fresh data.
Different types of data can have different TTL values.
| Data Type | Example TTL |
|---|---|
| Static configuration | Hours |
| Product catalog | Minutes |
| News articles | Minutes |
| User dashboard | Short |
| Frequently changing data | Seconds |
| Real-time information | Little or no caching |
These are examples rather than universal rules. The correct TTL depends on how frequently the underlying data changes and how much stale data your application can tolerate.
Common API Caching Strategies
There are several ways to design API caching.
Cache-Aside
Cache-aside is one of the most common approaches.
The application first checks the cache.
If the data exists:
Return cached data
If the data doesn’t exist:
Query database → Store result in cache → Return result
This gives the application control over what gets cached.
Read-Through Cache
With read-through caching, the application requests data from the caching layer.
If the cache doesn’t contain the data, the caching system retrieves it from the underlying data source.
The application doesn’t need to explicitly manage every cache miss.
Write-Through Cache
With write-through caching, data is written to the cache and underlying database together.
This can help keep cached data synchronized with the database.
However, every write may have additional overhead.
Write-Behind Cache
With write-behind caching, data is first written to the cache and later written to the database asynchronously.
This can improve write performance, but it introduces additional complexity and potential data-loss considerations if the cache fails before the data reaches persistent storage.
HTTP Cache-Control Headers
HTTP provides mechanisms that help control caching behavior.
One of the most important headers is:
Cache-Control
For example:
Cache-Control: max-age=300
This indicates that the response can be considered fresh for 300 seconds under the applicable caching rules.
Other directives include:
publicprivateno-cacheno-storemax-ages-maxagemust-revalidate
These directives allow developers to define how browsers and shared caches should handle responses.
What Is ETag?
ETag, short for Entity Tag, is an HTTP mechanism used to identify a specific version of a resource.
A server might return an ETag with a response.
When the client requests the resource again, it can send the ETag back using:
If-None-Match
If the resource hasn’t changed, the server can respond with:
304 Not Modified
Instead of sending the entire response again.
This can reduce unnecessary data transfer.
API Caching and Redis
Redis is one of the technologies commonly used for application-level caching.
A typical architecture might look like:
Client → Node.js API → Redis → PostgreSQL
The process could be:
- Client requests data.
- API checks Redis.
- If data exists, return it.
- If data doesn’t exist, query PostgreSQL.
- Store the result in Redis.
- Return the response.
This approach can significantly reduce repeated database queries for suitable workloads.
API Caching Example
Imagine an e-commerce API:
GET /api/products/123
Without caching:
Request → API → Database → Response
If 10,000 users request the same product information, the database may receive many identical queries.
With caching:
First request → API → Database → Cache → Response
Then:
Next request → API → Cache → Response
The database doesn’t need to process every identical read request.
API Caching for Mobile Applications
API caching isn’t limited to web applications.
Mobile applications can also benefit from caching.
For example, a mobile application may cache:
- User preferences
- Product information
- Categories
- Images
- Public content
- Previously loaded pages
Mobile caching can also help reduce network usage and improve the experience when the network connection is slow.
However, sensitive information should not be cached carelessly, particularly on shared or insecure storage.
API Caching for SaaS Applications
SaaS applications can receive large numbers of repeated API requests.
Caching can be useful for data such as:
- Subscription plans
- Feature configuration
- Public settings
- Dashboard statistics
- Product catalogs
- Organization-level configuration
- Frequently accessed reports
For multi-tenant SaaS applications, cache keys must be designed carefully.
For example, instead of:
dashboard:123
you might need a key structure that clearly separates tenants and users where appropriate.
Poor cache-key design can potentially expose one tenant’s data to another tenant.
What Data Should You Cache?
Not every API response should be cached.
Good candidates often include data that:
- Is requested frequently
- Changes relatively infrequently
- Is expensive to generate
- Can tolerate a small amount of staleness
- Is identical for many users
Examples include:
- Public product data
- Categories
- Public content
- Configuration
- Search results
- Frequently requested reports
What Data Should You Avoid Caching?
Be careful with highly sensitive or rapidly changing data.
Examples may include:
- Passwords
- Authentication credentials
- Payment information
- Private user information
- One-time tokens
- Highly dynamic account balances
- Real-time transaction information
For sensitive data, incorrect caching can create serious security and privacy problems.
Cache Invalidation
One of the hardest problems in caching is cache invalidation.
Suppose a product costs $50.
The API caches the product response.
Later, the price changes to $40.
If the cached response still says $50, users may receive outdated information.
This creates a consistency problem.
Common approaches include:
TTL-Based Expiration
Let the cache expire automatically after a certain period.
Manual Invalidation
Delete or update the cached value whenever the underlying data changes.
Versioned Cache Keys
Use a version number as part of the cache key.
Event-Based Invalidation
When data changes, publish an event that tells the caching system to invalidate the affected data.
The right approach depends on how frequently the data changes and how much stale information is acceptable.
Common API Caching Mistakes
Caching can improve performance, but poor implementation can create new problems.
Caching Everything
Not every endpoint benefits from caching.
Cache only data where caching provides a meaningful advantage.
Using Very Long TTLs
Long TTLs can cause users to receive outdated information.
Ignoring Cache Invalidation
If cached data isn’t invalidated when necessary, the application can return stale data.
Poor Cache Keys
A poorly designed key can cause incorrect data to be returned.
This is especially dangerous in multi-user and multi-tenant applications.
Caching Sensitive Data
Sensitive information should not be placed into shared caches without careful security controls.
No Cache Monitoring
Without monitoring, you may not know whether caching is actually improving performance.
API Caching Best Practices
A reliable API caching strategy should include:
1. Cache Only Valuable Data
Start with endpoints that have high request volume or expensive processing.
2. Choose TTL Carefully
Match the TTL to how frequently the underlying data changes.
3. Design Cache Keys Carefully
Include the parameters that actually affect the response.
4. Plan Cache Invalidation
Don’t treat invalidation as an afterthought.
5. Protect Sensitive Information
Understand whether cached responses can be accessed by other users or systems.
6. Monitor Cache Performance
Track metrics such as:
- Cache hit rate
- Cache miss rate
- Response latency
- Cache size
- Evictions
- Error rate
7. Have a Fallback
Your application should be able to retrieve data from the original source if the cache becomes unavailable, when appropriate.
8. Avoid Over-Caching
Caching should solve a performance problem, not introduce unnecessary architectural complexity.
How to Measure API Cache Performance
Several metrics can help determine whether your caching strategy is effective.
Cache Hit Rate
A simple formula is:
Cache Hit Rate = Cache Hits ÷ Total Requests × 100
For example, if 9,000 out of 10,000 requests are served from the cache:
Cache Hit Rate = 90%
A high hit rate can indicate that frequently requested data is being reused effectively.
However, a high cache-hit rate isn’t automatically good if the cached data is stale or inappropriate to cache.
API Caching vs Database Optimization
Caching and database optimization solve different problems.
If your database query is inefficient, you should usually optimize the query rather than simply adding a cache.
Database optimization can include:
- Indexing
- Query optimization
- Better database design
- Connection pooling
- Pagination
Caching can then be added when repeated requests still justify it.
A good architecture often combines both.
API Caching vs CDN Caching
These concepts are related but not identical.
API caching can happen at the application or infrastructure layer and may involve dynamic responses.
CDN caching typically stores cacheable responses closer to users at edge locations.
For a globally distributed application, you might use both:
User → CDN Cache → API → Application Cache → Database
Each layer can reduce unnecessary work.
When Should You Implement API Caching?
You should consider API caching when:
- API requests are repeated frequently
- Database queries are expensive
- Response generation takes significant time
- Data doesn’t change frequently
- Application traffic is increasing
- You need lower response latency
- Infrastructure costs are increasing
You may not need caching for:
- Very small applications
- Low-traffic APIs
- Highly dynamic data
- One-time requests
- Endpoints where caching adds more complexity than value
Start with measurements rather than adding caching everywhere.
Conclusion
API caching is an important technique for improving the performance and scalability of modern applications.
By temporarily storing frequently requested API responses, applications can reduce database queries, lower server workload, decrease response times, and handle more traffic efficiently.
However, caching isn’t simply about storing data.
A successful caching strategy requires careful decisions around:
- What to cache
- Where to cache
- Cache keys
- TTL
- Cache invalidation
- Security
- Consistency
- Monitoring
For small applications, simple HTTP or application-level caching may be enough. As applications grow, technologies such as Redis, CDNs, reverse proxies, and distributed caching can become valuable parts of the architecture.
The most important principle is simple:
Cache the right data, for the right amount of time, at the right layer.
When implemented correctly, API caching can become one of the most effective ways to improve application performance without continuously increasing backend infrastructure.