Image classification is one of the most popular applications of artificial intelligence and deep learning.
It allows a computer to look at an image and predict what that image contains.
For example, an image classification model can identify whether an image contains:
- A cat
- A dog
- A car
- A flower
- A handwritten digit
- A type of food
- A product category
Modern image classification systems are commonly built using Convolutional Neural Networks, or CNNs.
One of the best frameworks for building CNN-based image classifiers is PyTorch.
In this beginner-friendly tutorial, you will learn how to build an image classification model using Python and PyTorch.
We will cover:
- What image classification is
- How image classification works
- How to install PyTorch
- How to load an image dataset
- How to prepare images
- How to build a CNN
- How to train the model
- How to calculate accuracy
- How to make predictions
- How to save and load the trained model
- How to improve model performance
By the end of this guide, you will understand the complete image classification workflow in PyTorch.
What Is Image Classification?
Image classification is a computer vision task where a machine-learning model assigns an image to one of several predefined categories.
For example, suppose we have these classes:
Cat
Dog
Horse
Bird
The model receives an image and predicts which category it belongs to.
A result might look like:
Cat = 0.92
Dog = 0.05
Horse = 0.02
Bird = 0.01
The model predicts:
Cat
because it has the highest probability.
How Does Image Classification Work?
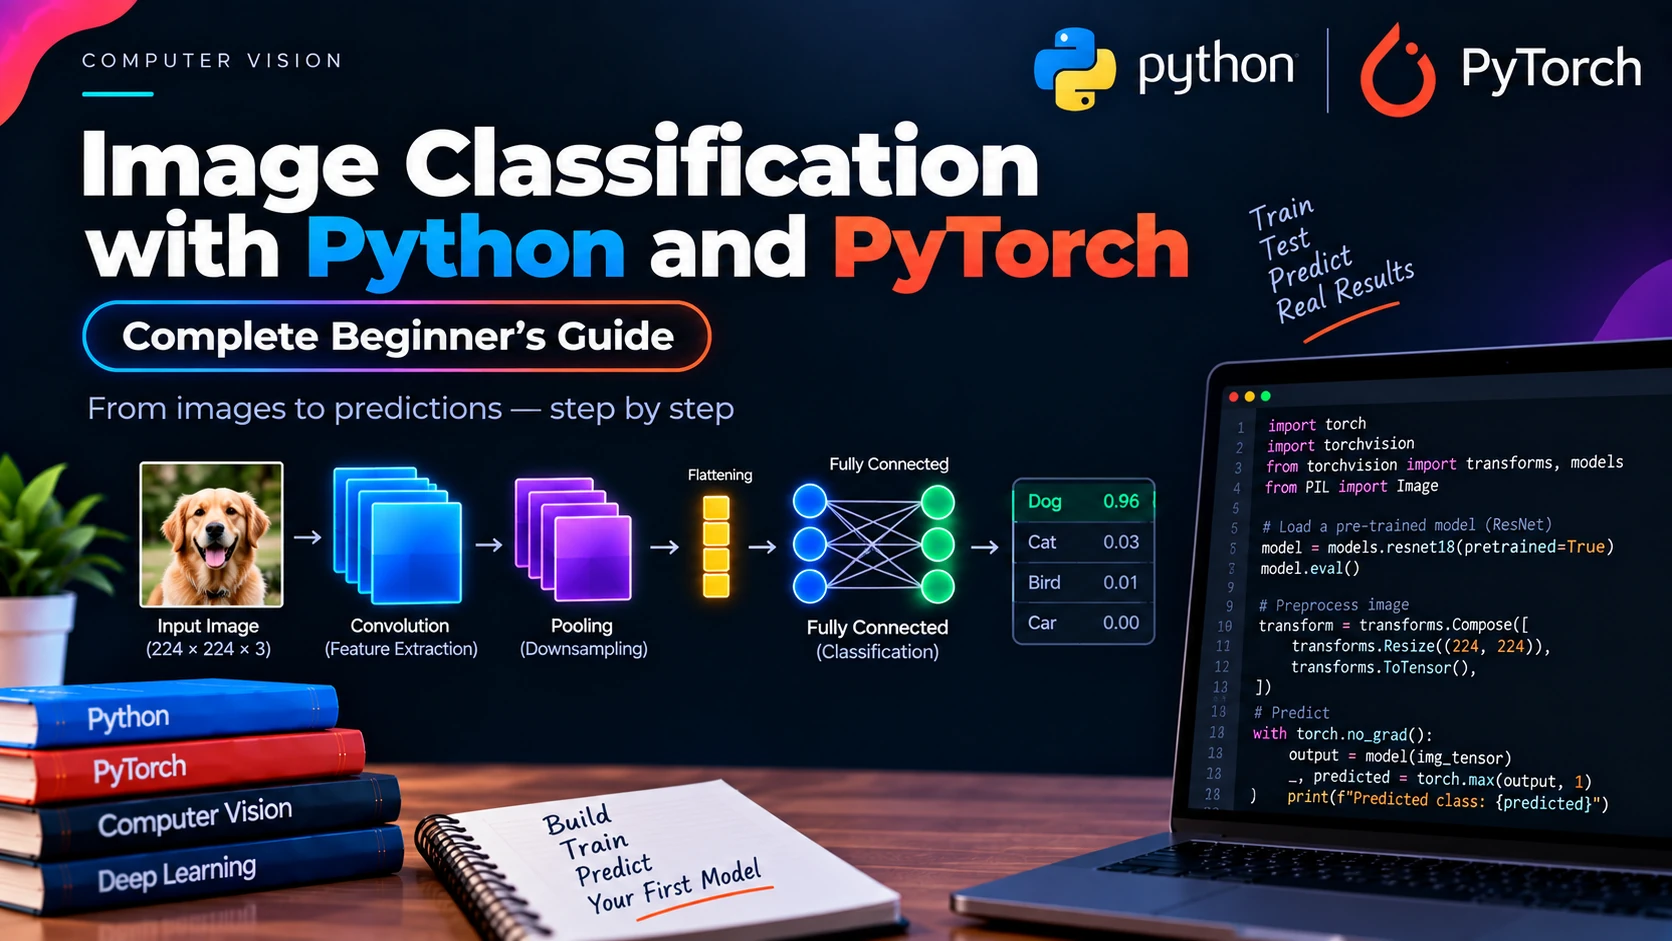
A typical deep-learning image classifier follows this workflow:
Image Dataset
      ↓
Image Preprocessing
      ↓
Convert Images to Tensors
      ↓
CNN Model
      ↓
Feature Extraction
      ↓
Classification Layer
      ↓
Prediction
During training:
Input Image
    ↓
CNN
    ↓
Prediction
    ↓
Compare with Correct Label
    ↓
Calculate Loss
    ↓
Backpropagation
    ↓
Update Weights
    ↓
Repeat
Over time, the model learns which visual patterns are useful for distinguishing different classes.
Why Use PyTorch for Image Classification?
PyTorch is a popular choice because it provides:
- Tensor operations
- Automatic differentiation
- Neural-network layers
- CNN layers
- GPU acceleration
- Dataset utilities
- DataLoader
- Pretrained models
- Image transformation tools
It also works closely with:
torchvision
which provides image datasets, models, and preprocessing utilities.
What Will We Build?
In this tutorial, we will build a simple image classifier using the CIFAR-10 dataset.
CIFAR-10 contains small color images belonging to 10 classes:
Airplane
Automobile
Bird
Cat
Deer
Dog
Frog
Horse
Ship
Truck
Each image is:
32 × 32 pixels
with three color channels:
Red
Green
Blue
This makes CIFAR-10 a good dataset for beginners.
Step 1: Install Python and PyTorch
First, make sure Python is installed.
Check your version:
python --version
or:
python3 --version
Now install PyTorch and TorchVision:
pip install torch torchvision
We will also use Matplotlib for visualization:
pip install matplotlib
After installation, test PyTorch:
import torch

print(torch.__version__)
If you see a version number, PyTorch is installed correctly.
Step 2: Import Required Libraries
Create a Python file such as:
image_classifier.py
Now import the required libraries:
import torch
import torch.nn as nn
import torch.optim as optim

import torchvision
import torchvision.transforms as transforms

import matplotlib.pyplot as plt
We will use:
torch
for tensor operations.
torch.nn
for neural-network layers.
torch.optim
for optimization.
torchvision
for image datasets.
transforms
for image preprocessing.
Step 3: Prepare the Image Transformations
Neural networks do not directly understand image files.
Images must be converted into tensors.
Create a transformation:
transform = transforms.Compose([
    transforms.ToTensor()
])
ToTensor() converts an image into a PyTorch tensor.
Pixel values are also converted into floating-point values, typically in the range:
0 to 1
Step 4: Normalize the Images
Normalization often helps neural networks train more effectively.
For CIFAR-10, we can use:
transform = transforms.Compose([
    transforms.ToTensor(),

    transforms.Normalize(
        (0.5, 0.5, 0.5),
        (0.5, 0.5, 0.5)
    )
])
This normalizes each RGB channel.
The transformed values will approximately fall between:
-1 and 1
Normalization can improve training stability.
Step 5: Download the CIFAR-10 Dataset
TorchVision can automatically download CIFAR-10.
Create the training dataset:
train_dataset = torchvision.datasets.CIFAR10(
    root="./data",
    train=True,
    download=True,
    transform=transform
)
Create the test dataset:
test_dataset = torchvision.datasets.CIFAR10(
    root="./data",
    train=False,
    download=True,
    transform=transform
)
Here:
train=True
loads training images.
train=False
loads test images.
Step 6: Create DataLoaders
Instead of sending all images into the model at once, we process them in smaller groups called batches.
Create a DataLoader:
train_loader = torch.utils.data.DataLoader(
    train_dataset,
    batch_size=64,
    shuffle=True
)
And the test loader:
test_loader = torch.utils.data.DataLoader(
    test_dataset,
    batch_size=64,
    shuffle=False
)
The batch size is:
64
This means the model processes 64 images at a time.
Why Use DataLoader?
The PyTorch DataLoader helps with:
- Batch processing
- Shuffling
- Efficient data loading
- Large datasets
- Training loops
For training data, we normally use:
shuffle=True
This changes the order of images between epochs.
For test data:
shuffle=False
is usually sufficient.
Step 7: Define the Class Names
CIFAR-10 contains 10 classes.
Create a list:
classes = (
    "airplane",
    "automobile",
    "bird",
    "cat",
    "deer",
    "dog",
    "frog",
    "horse",
    "ship",
    "truck"
)
Later, we will convert model predictions into these class names.
Step 8: Understand Image Tensor Shape
Let’s inspect one batch:
images, labels = next(iter(train_loader))

print(images.shape)
print(labels.shape)
You may see:
torch.Size([64, 3, 32, 32])
This means:
64 = Batch Size
3 = RGB Channels
32 = Image Height
32 = Image Width
PyTorch usually represents image batches in this format:
Batch × Channels × Height × Width
Step 9: Display a Sample Image
Before training, it is useful to inspect your data.
Because the image was normalized, we should reverse that normalization before displaying it.
def show_image(image):

    image = image / 2 + 0.5

    image = image.numpy()

    plt.imshow(
        image.transpose(1, 2, 0)
    )

    plt.show()
Now display one image:
image, label = train_dataset[0]

show_image(image)

print(classes[label])
You should see an image along with its class name.
Step 10: Build the CNN Model
Now let’s create a Convolutional Neural Network.
class CNN(nn.Module):

    def __init__(self):
        super().__init__()

        self.conv1 = nn.Conv2d(
            3,
            32,
            kernel_size=3,
            padding=1
        )

        self.conv2 = nn.Conv2d(
            32,
            64,
            kernel_size=3,
            padding=1
        )

        self.pool = nn.MaxPool2d(
            kernel_size=2,
            stride=2
        )

        self.relu = nn.ReLU()

        self.fc1 = nn.Linear(
            64 * 8 * 8,
            128
        )

        self.fc2 = nn.Linear(
            128,
            10
        )

    def forward(self, x):

        x = self.conv1(x)
        x = self.relu(x)
        x = self.pool(x)

        x = self.conv2(x)
        x = self.relu(x)
        x = self.pool(x)

        x = torch.flatten(x, 1)

        x = self.fc1(x)
        x = self.relu(x)

        x = self.fc2(x)

        return x
This is our image classification model.
Understanding the CNN Architecture
Our CNN looks like this:
Input Image
32 × 32 × 3
      ↓
Convolution
3 → 32 Channels
      ↓
ReLU
      ↓
Max Pooling
      ↓
Convolution
32 → 64 Channels
      ↓
ReLU
      ↓
Max Pooling
      ↓
Flatten
      ↓
Fully Connected Layer
      ↓
128 Neurons
      ↓
Output
10 Classes
Let’s understand each layer.
First Convolution Layer
The first layer is:
nn.Conv2d(
    3,
    32,
    kernel_size=3,
    padding=1
)
The input has:
3 channels
because CIFAR-10 images are RGB.
The layer produces:
32 feature maps
using 32 learned filters.
Each filter is:
3 × 3
First Pooling Layer
After convolution and ReLU:
self.pool(x)
reduces the image dimensions.
The input size is:
32 × 32
After pooling:
16 × 16
This reduces computation while preserving important features.
Second Convolution Layer
The second convolution layer is:
nn.Conv2d(
    32,
    64,
    kernel_size=3,
    padding=1
)
It receives 32 feature maps and creates 64 new feature maps.
After another pooling operation:
16 × 16
becomes:
8 × 8
Therefore, the final feature dimensions are:
64 × 8 × 8
Flattening the Features
Before sending features into a fully connected layer, we flatten them.
x = torch.flatten(x, 1)
The size becomes:
64 × 8 × 8
which equals:
4096
features per image.
Fully Connected Layers
The first fully connected layer is:
nn.Linear(
    64 * 8 * 8,
    128
)
It converts 4096 features into 128 learned representations.
The final layer is:
nn.Linear(
    128,
    10
)
because CIFAR-10 contains 10 classes.
Step 11: Create the Model
Create an instance:
model = CNN()
Print it:
print(model)
You should see the complete architecture.
Step 12: Use GPU If Available
Training neural networks can be much faster on supported GPUs.
Create a device:
device = torch.device(
    "cuda" if torch.cuda.is_available()
    else "cpu"
)
Move the model:
model = model.to(device)
Print the device:
print("Using device:", device)
You may see:
Using device: cuda
or:
Using device: cpu
Apple Silicon Support
If you use a modern Apple Silicon Mac, PyTorch may support the MPS backend.
You can detect it using:
if torch.cuda.is_available():

    device = torch.device("cuda")

elif torch.backends.mps.is_available():

    device = torch.device("mps")

else:

    device = torch.device("cpu")
Then move the model:
model = model.to(device)
This allows compatible Apple GPUs to accelerate many PyTorch operations.
Step 13: Define the Loss Function
Image classification with multiple classes commonly uses:
criterion = nn.CrossEntropyLoss()
Cross-entropy loss compares the model’s output with the correct class.
We do not need to manually apply Softmax before CrossEntropyLoss.
PyTorch handles the necessary calculations internally.
Step 14: Create the Optimizer
Now create an optimizer.
We will use Adam:
optimizer = optim.Adam(
    model.parameters(),
    lr=0.001
)
The optimizer updates the model’s parameters during training.
Here:
Learning Rate = 0.001
Step 15: Train the Image Classifier
Now we can train the CNN.
epochs = 10

for epoch in range(epochs):

    model.train()

    running_loss = 0.0

    for images, labels in train_loader:

        images = images.to(device)
        labels = labels.to(device)

        optimizer.zero_grad()

        outputs = model(images)

        loss = criterion(
            outputs,
            labels
        )

        loss.backward()

        optimizer.step()

        running_loss += loss.item()

    print(
        f"Epoch {epoch + 1}/{epochs}, "
        f"Loss: "
        f"{running_loss / len(train_loader):.4f}"
    )
This is the main training loop.
Understanding the Training Loop
Every training step performs:
Load Image Batch
      ↓
Move Data to Device
      ↓
Forward Pass
      ↓
Generate Predictions
      ↓
Calculate Loss
      ↓
Backpropagation
      ↓
Update Weights
Let’s understand the important lines.
optimizer.zero_grad()
Before calculating new gradients:
optimizer.zero_grad()
clears the previous gradients.
PyTorch accumulates gradients by default, so this is an important step.
Forward Pass
This line:
outputs = model(images)
sends the image batch through the CNN.
The network extracts visual features and generates class scores.
Calculate Loss
Next:
loss = criterion(
    outputs,
    labels
)
compares the predictions with the correct class labels.
The model tries to minimize this value.
Backpropagation
This line:
loss.backward()
calculates gradients for the trainable parameters.
These gradients show how parameters contributed to the prediction error.
Update Model Parameters
This line:
optimizer.step()
updates the model’s weights.
The CNN gradually learns better filters and classification patterns.
Step 16: Evaluate Model Accuracy
After training, evaluate the classifier using test images.
model.eval()

correct = 0
total = 0

with torch.no_grad():

    for images, labels in test_loader:

        images = images.to(device)
        labels = labels.to(device)

        outputs = model(images)

        _, predicted = torch.max(
            outputs,
            1
        )

        total += labels.size(0)

        correct += (
            predicted == labels
        ).sum().item()


accuracy = (
    100 * correct / total
)

print(
    f"Test Accuracy: "
    f"{accuracy:.2f}%"
)
This calculates the percentage of correctly classified test images.
What Does torch.max() Do?
The model outputs 10 scores.
For example:
Airplane = 0.5
Automobile = 1.2
Bird = 0.9
Cat = 4.8
Dog = 2.1
...
We need the class with the highest score.
This line:
_, predicted = torch.max(
    outputs,
    1
)
returns the index of the highest score.
If the highest score corresponds to:
3
and class index 3 represents:
cat
the model predicts:
Cat
Step 17: Make a Prediction on One Image
Let’s test one image.
image, label = test_dataset[0]

input_image = image.unsqueeze(0)

input_image = input_image.to(device)
The model expects a batch dimension.
Originally:
3 × 32 × 32
After unsqueeze(0):
1 × 3 × 32 × 32
Now predict:
model.eval()

with torch.no_grad():

    output = model(input_image)

    _, predicted = torch.max(
        output,
        1
    )

print(
    "Predicted:",
    classes[predicted.item()]
)

print(
    "Actual:",
    classes[label]
)
You might see:
Predicted: cat
Actual: cat
Step 18: Get Prediction Probabilities
If you want probabilities, apply Softmax:
with torch.no_grad():

    output = model(input_image)

    probabilities = torch.softmax(
        output,
        dim=1
    )
Now get the highest probability:
confidence, predicted = torch.max(
    probabilities,
    1
)

print(
    classes[predicted.item()]
)

print(
    confidence.item()
)
You might get:
cat
0.87
This means the model predicts a cat with approximately:
87% confidence
Complete Image Classification Code
Here is the entire example in one place:
import torch
import torch.nn as nn
import torch.optim as optim

import torchvision
import torchvision.transforms as transforms


transform = transforms.Compose([
    transforms.ToTensor(),

    transforms.Normalize(
        (0.5, 0.5, 0.5),
        (0.5, 0.5, 0.5)
    )
])


train_dataset = torchvision.datasets.CIFAR10(
    root="./data",
    train=True,
    download=True,
    transform=transform
)


test_dataset = torchvision.datasets.CIFAR10(
    root="./data",
    train=False,
    download=True,
    transform=transform
)


train_loader = torch.utils.data.DataLoader(
    train_dataset,
    batch_size=64,
    shuffle=True
)


test_loader = torch.utils.data.DataLoader(
    test_dataset,
    batch_size=64,
    shuffle=False
)


classes = (
    "airplane",
    "automobile",
    "bird",
    "cat",
    "deer",
    "dog",
    "frog",
    "horse",
    "ship",
    "truck"
)


class CNN(nn.Module):

    def __init__(self):
        super().__init__()

        self.conv1 = nn.Conv2d(
            3,
            32,
            kernel_size=3,
            padding=1
        )

        self.conv2 = nn.Conv2d(
            32,
            64,
            kernel_size=3,
            padding=1
        )

        self.pool = nn.MaxPool2d(
            2,
            2
        )

        self.relu = nn.ReLU()

        self.fc1 = nn.Linear(
            64 * 8 * 8,
            128
        )

        self.fc2 = nn.Linear(
            128,
            10
        )

    def forward(self, x):

        x = self.pool(
            self.relu(
                self.conv1(x)
            )
        )

        x = self.pool(
            self.relu(
                self.conv2(x)
            )
        )

        x = torch.flatten(
            x,
            1
        )

        x = self.relu(
            self.fc1(x)
        )

        x = self.fc2(x)

        return x


if torch.cuda.is_available():

    device = torch.device("cuda")

elif torch.backends.mps.is_available():

    device = torch.device("mps")

else:

    device = torch.device("cpu")


model = CNN().to(device)


criterion = nn.CrossEntropyLoss()


optimizer = optim.Adam(
    model.parameters(),
    lr=0.001
)


epochs = 10


for epoch in range(epochs):

    model.train()

    running_loss = 0.0

    for images, labels in train_loader:

        images = images.to(device)
        labels = labels.to(device)

        optimizer.zero_grad()

        outputs = model(images)

        loss = criterion(
            outputs,
            labels
        )

        loss.backward()

        optimizer.step()

        running_loss += loss.item()

    print(
        f"Epoch {epoch + 1}/{epochs}, "
        f"Loss: "
        f"{running_loss / len(train_loader):.4f}"
    )


model.eval()

correct = 0
total = 0


with torch.no_grad():

    for images, labels in test_loader:

        images = images.to(device)
        labels = labels.to(device)

        outputs = model(images)

        _, predicted = torch.max(
            outputs,
            1
        )

        total += labels.size(0)

        correct += (
            predicted == labels
        ).sum().item()


accuracy = (
    100 * correct / total
)


print(
    f"Test Accuracy: "
    f"{accuracy:.2f}%"
)
This is a complete working example of basic image classification with Python and PyTorch.
Step 19: Save the Trained Model
Once your model is trained, save its learned parameters:
torch.save(
    model.state_dict(),
    "cifar10_cnn.pth"
)
The file:
cifar10_cnn.pth
contains the trained weights.
You can reuse the model later without retraining.
Step 20: Load the Saved Model
Create the same architecture:
model = CNN()
Load the parameters:
model.load_state_dict(
    torch.load(
        "cifar10_cnn.pth",
        map_location=device
    )
)
Move it to the device:
model = model.to(device)
Switch to evaluation mode:
model.eval()
Now you can make predictions.
Train Mode vs Evaluation Mode
During training, use:
model.train()
During testing or inference:
model.eval()
This is important because some neural-network layers behave differently during training and evaluation.
Examples include:
- Dropout
- Batch normalization
How to Improve Image Classification Accuracy
Our model is intentionally simple.
There are several ways to improve it.
Add More Convolution Layers
A deeper network can learn more complex features.
For example:
Edges
↓
Textures
↓
Shapes
↓
Object Parts
↓
Objects
However, deeper does not always mean better.
Add Batch Normalization
Batch normalization can improve training stability.
For example:
nn.BatchNorm2d(32)
A CNN block might look like:
nn.Conv2d(3, 32, 3, padding=1)
nn.BatchNorm2d(32)
nn.ReLU()
Add Dropout
Dropout can help reduce overfitting.
For example:
self.dropout = nn.Dropout(0.5)
During training, dropout randomly disables some activations.
This encourages the network to learn more robust features.
Use Data Augmentation
Data augmentation creates modified versions of training images.
For example:
transform = transforms.Compose([

    transforms.RandomHorizontalFlip(),

    transforms.RandomCrop(
        32,
        padding=4
    ),

    transforms.ToTensor(),

    transforms.Normalize(
        (0.5, 0.5, 0.5),
        (0.5, 0.5, 0.5)
    )
])
This can help models generalize better.
Common Data Augmentation Techniques
Popular image transformations include:
Horizontal Flip
Random Crop
Rotation
Color Changes
Random Resize
Random Erasing
These techniques help the model see more diverse versions of the same data.
Use More Training Epochs
Increasing the number of epochs may improve performance.
For example:
epochs = 30
instead of:
epochs = 10
But training for too long may lead to overfitting.
Always monitor validation performance.
Tune the Learning Rate
The learning rate strongly affects training.
Try values such as:
0.01
0.001
0.0001
If it is too high, training may become unstable.
If it is too low, training may be very slow.
Try Different Optimizers
Common optimizers include:
SGD
Adam
AdamW
RMSprop
For example:
optimizer = optim.SGD(
    model.parameters(),
    lr=0.01,
    momentum=0.9
)
Different models may perform better with different optimizers.
What Is Overfitting?
Overfitting happens when the model performs very well on training data but poorly on unseen data.
For example:
Training Accuracy = 98%
Test Accuracy = 70%
This may indicate overfitting.
Possible solutions include:
- Data augmentation
- Dropout
- Weight decay
- More training data
- Smaller model
- Early stopping
What Is Underfitting?
Underfitting happens when the model cannot learn the training data well.
For example:
Training Accuracy = 55%
Test Accuracy = 52%
Possible causes include:
- Model too simple
- Too few epochs
- Poor learning rate
- Poor data preprocessing
- Weak training setup
Training, Validation, and Test Data
In real-world projects, datasets should usually be divided into:
Training Set
Validation Set
Test Set
The training set teaches the model.
The validation set helps tune parameters and monitor performance.
The test set measures final performance on unseen data.
A possible split is:
70% Training
15% Validation
15% Testing
The exact ratio depends on the amount and type of data available.
Accuracy Is Not Always Enough
Accuracy is useful, but it is not always the best metric.
Suppose a medical dataset contains:
95% Healthy
5% Disease
A model that predicts:
Healthy
for every image would get:
95% Accuracy
but it would fail to detect any disease cases.
Other metrics include:
- Precision
- Recall
- F1 Score
- Confusion Matrix
- ROC-AUC
Choosing the right metric depends on the task.
Image Classification vs Object Detection
These two tasks are different.
Image Classification
Predicts what the entire image contains.
Example:
Image
↓
Dog
Object Detection
Predicts both:
What objects are present
and:
Where they are located
For example:
2 People
1 Car
1 Bicycle
with bounding boxes.
Image Classification vs Image Segmentation
Image segmentation performs classification at the pixel level.
For example, every pixel might be labeled as:
Road
Car
Person
Sky
Building
This provides more detailed visual understanding than standard classification.
CNN vs Pretrained Model
You do not always need to build a CNN from scratch.
PyTorch provides many pretrained models through TorchVision.
Examples include:
ResNet
MobileNet
EfficientNet
Vision Transformer
ConvNeXt
You can use a pretrained model and adapt it to your own dataset.
This is called:
Transfer Learning
What Is Transfer Learning?
Transfer learning means using a model that has already learned useful features from a large dataset.
Instead of:
Random Model
↓
Train Everything From Scratch
you can use:
Pretrained Model
↓
Replace Final Classification Layer
↓
Train on Your Dataset
This often gives better results with less training data.
Transfer Learning Example with ResNet
Load a pretrained model:
from torchvision import models


model = models.resnet18(
    weights="DEFAULT"
)
Replace the final layer:
model.fc = nn.Linear(
    model.fc.in_features,
    10
)
Now the model can be fine-tuned for a 10-class classification problem.
For beginners, transfer learning is one of the most useful skills to learn after building a CNN from scratch.
Real-World Applications of Image Classification
Image classification is used in many industries.
Healthcare
AI models can help classify:
- X-rays
- Skin images
- Eye scans
- Medical imagery
Such systems require rigorous validation and professional medical oversight.
Agriculture
Models can classify:
- Plant diseases
- Crop types
- Fruit quality
- Leaf conditions
Manufacturing
AI can identify:
Defective Product
Normal Product
Retail
Image classification can identify product categories.
For example:
Shoes
Shirts
Phones
Furniture
Wildlife Monitoring
Camera images can be automatically classified by animal species.
Document Processing
AI can classify:
- Receipts
- Invoices
- Identity documents
- Forms
Content Moderation
Computer vision can help categorize visual content before further review.
Beginner Image Classification Projects
After completing this tutorial, try:
- Cat vs dog classifier
- Flower classifier
- Fruit classifier
- Plant disease detector
- Vehicle classifier
- Fashion classifier
- Handwritten digit classifier
- Food classifier
- Animal species classifier
- Waste classification model
These projects will help you understand computer vision much faster.
Image Classification Learning Roadmap
A practical learning order is:
Python
  ↓
NumPy
  ↓
PyTorch
  ↓
Neural Networks
  ↓
CNN Basics
  ↓
Image Tensors
  ↓
TorchVision
  ↓
Dataset and DataLoader
  ↓
Build CNN
  ↓
Train Image Classifier
  ↓
Data Augmentation
  ↓
Transfer Learning
  ↓
ResNet
  ↓
Object Detection
  ↓
Image Segmentation
Common Beginner Mistakes
Forgetting to Normalize Images
Proper preprocessing can make training more stable.
Wrong Image Shape
PyTorch expects image batches in:
Batch × Channels × Height × Width
Applying Softmax Before CrossEntropyLoss
You usually should not manually apply Softmax before:
nn.CrossEntropyLoss()
Use raw logits instead.
Forgetting model.eval()
Use:
model.eval()
during evaluation.
Forgetting torch.no_grad()
During inference:
with torch.no_grad():
reduces unnecessary gradient computation.
Training Only on CPU
For larger models, compatible accelerators can significantly improve training speed.
Testing on Training Data
Always evaluate with unseen data.
Frequently Asked Questions
What is image classification in Python?
Image classification is the process of using Python and machine-learning libraries to train a model that assigns images to predefined categories.
Can PyTorch be used for image classification?
Yes. PyTorch is widely used for image classification and provides CNN layers, datasets, image transformations, pretrained models, and GPU support.
What is TorchVision?
TorchVision is a PyTorch package that provides image datasets, transformations, model architectures, and other computer-vision utilities.
Why are CNNs used for image classification?
CNNs can automatically learn visual features such as edges, textures, shapes, and object parts.
What dataset is good for beginners?
Popular beginner datasets include:
MNIST
Fashion-MNIST
CIFAR-10
Do I need a GPU?
No. Small models can be trained on a CPU.
However, a GPU can significantly speed up larger deep-learning models.
What is the best loss function for image classification?
For many multi-class classification problems, a common choice is:
nn.CrossEntropyLoss()
Should I build a CNN from scratch or use transfer learning?
Build a small CNN from scratch first to understand the concepts.
After that, learn transfer learning because it is commonly used in practical projects.
Final Thoughts
Image classification is one of the best ways to start learning computer vision with deep learning.
The basic workflow is:
Collect Images
      ↓
Prepare Dataset
      ↓
Transform Images
      ↓
Create DataLoader
      ↓
Build CNN
      ↓
Choose Loss Function
      ↓
Choose Optimizer
      ↓
Train Model
      ↓
Evaluate Accuracy
      ↓
Make Predictions
      ↓
Save Model
PyTorch makes this process easier by providing tools such as:
- Tensors
torch.nntorch.optim- TorchVision
- Dataset
- DataLoader
- Automatic differentiation
- GPU support
Start with simple datasets such as CIFAR-10 or Fashion-MNIST.
Once you understand how the complete training pipeline works, move toward:
- Data augmentation
- Transfer learning
- ResNet
- EfficientNet
- Vision Transformers
- Object detection
- Image segmentation
The most important thing is not to memorize every line of PyTorch code.
Understand how the complete pipeline works:
Images become tensors, CNNs extract features, the model makes predictions, the loss measures errors, and backpropagation helps the network improve.
That foundation will make advanced computer vision much easier to learn.