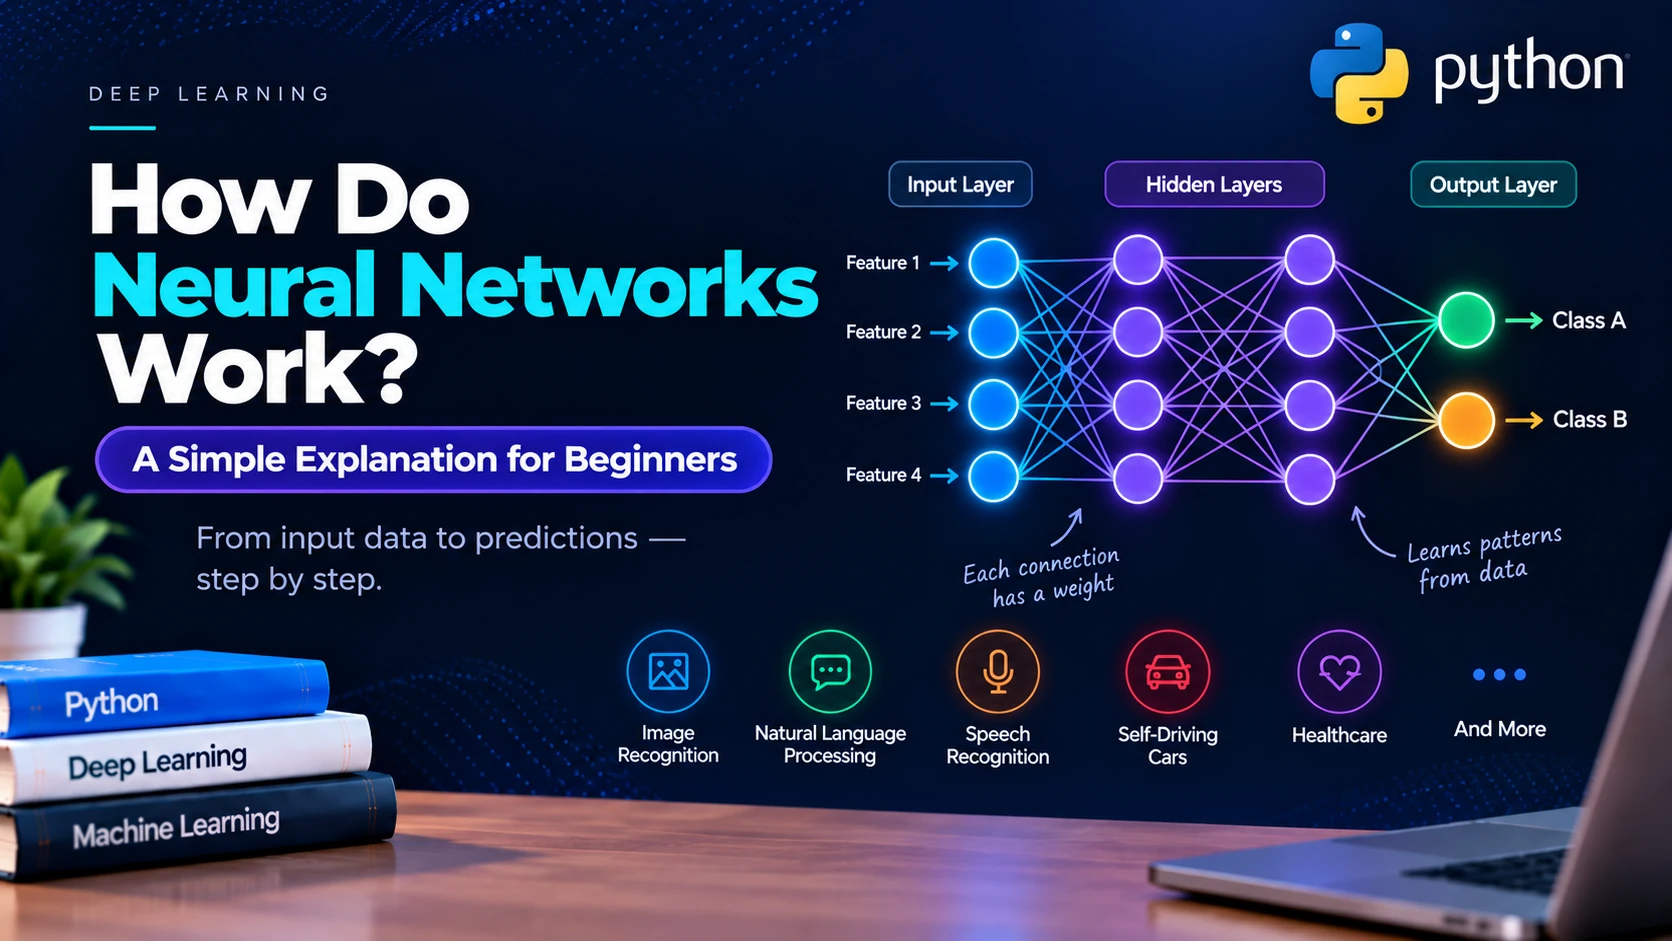
Neural networks are one of the most important technologies behind modern artificial intelligence. They help computers recognize images, understand language, make predictions, generate text, process speech, and solve complex problems.
Technologies such as ChatGPT, image recognition, recommendation systems, voice assistants, autonomous driving systems, and generative AI rely heavily on neural networks.
But how does a neural network actually work?
In this beginner-friendly guide, we’ll understand neural networks step by step, from neurons and layers to weights, activation functions, forward propagation, backpropagation, and training.
What Is a Neural Network?
A neural network is a machine learning model designed to identify patterns and relationships within data.
It consists of interconnected computational units called neurons or nodes.
These neurons are organized into layers and work together to transform input data into useful predictions.
A simple neural network usually contains three types of layers:
- Input layer
- Hidden layer or layers
- Output layer
For example, suppose we want to build an AI system that determines whether an image contains a cat or a dog.
The image is provided to the input layer.
The hidden layers analyze different patterns in the image.
The output layer produces the final prediction.
The result might look like:
Cat: 95%
Dog: 5%
The network therefore predicts that the image most likely contains a cat.
How Do Neural Networks Work?
A neural network works by passing information through multiple layers of neurons.
The basic process is:
Input Data → Weighted Calculations → Activation Functions → Hidden Layers → Output → Error Calculation → Learning
During training, the network repeatedly adjusts its internal parameters until its predictions become more accurate.
Let’s understand each part.
1. Input Layer Receives Data
The first part of a neural network is the input layer.
It receives the information that the network needs to process.
For example, imagine we want to predict the price of a house.
Our input data might include:
- House size
- Number of bedrooms
- Number of bathrooms
- Location
- Property age
Each feature can become an input to the neural network.
Suppose we have:
Size = 2000 sq. ft.
Bedrooms = 3
Bathrooms = 2
Age = 5 years
These values enter the neural network through input neurons.
For images, the inputs might be pixel values.
For text, they might be numerical representations of words or tokens.
2. Inputs Are Multiplied by Weights
Connections between neurons have values called weights.
Weights determine how important different pieces of information are.
Imagine our house-price model learns that:
- Location is extremely important.
- House size is very important.
- Number of bedrooms is moderately important.
- Property age has a smaller influence.
The network can represent these differences through weights.
Conceptually, a neuron performs calculations similar to:
Input × Weight
For several inputs:
(x1 × w1) + (x2 × w2) + (x3 × w3)
Where:
xrepresents input values.wrepresents weights.
During training, the neural network learns better weight values automatically.
3. Bias Is Added
Neural networks also use another parameter called bias.
Bias gives neurons additional flexibility when learning patterns.
The calculation becomes:
z = (x1 × w1) + (x2 × w2) + ... + b
Where:
x= inputw= weightb= biasz= calculated value
Both weights and biases are adjusted while the neural network learns.
4. Activation Function Processes the Result
After calculating the weighted sum, a neuron usually sends the result through an activation function.
Activation functions help neural networks learn complex and nonlinear relationships.
Without nonlinear activation functions, stacking many layers would provide far less expressive power.
Some common activation functions include:
ReLU
ReLU (Rectified Linear Unit) is one of the most commonly used activation functions in neural networks.
Its basic behavior is:
f(x) = max(0, x)
If the input is negative, ReLU returns zero.
If the input is positive, it returns the input.
For example:
Input: -4 → Output: 0
Input: 7 → Output: 7
ReLU is widely used in hidden layers.
Sigmoid
Sigmoid transforms a value into a number between 0 and 1.
This can be useful for binary classification outputs.
For example:
0.92
could represent a 92% predicted probability for the positive class.
Softmax
Softmax is commonly used for multi-class classification.
Suppose an AI system recognizes animals.
Its output might be:
Cat = 0.75
Dog = 0.20
Horse = 0.05
The model predicts Cat because it has the highest probability.
Understanding Neural Network Layers
Layers are fundamental building blocks of neural networks.
Input Layer
The input layer receives the original data.
For an image, this might represent pixel information.
For a prediction system, it could represent features such as:
Age
Income
Location
Purchase History
The input layer primarily provides these values to the next layer.
Hidden Layers
Hidden layers perform most of the intermediate computations.
A simple neural network might look like:
Input Layer
      ↓
Hidden Layer
      ↓
Output Layer
A deeper neural network might contain many hidden layers:
Input
  ↓
Hidden Layer 1
  ↓
Hidden Layer 2
  ↓
Hidden Layer 3
  ↓
Hidden Layer 4
  ↓
Output
Networks with multiple processing layers are associated with deep learning.
Different layers can learn different levels of representation.
For example, in image recognition, earlier layers may respond to simple visual patterns such as edges, while deeper layers can combine learned features into more complex representations.
Output Layer
The output layer generates the model’s prediction.
The structure of this layer depends on the problem.
For binary classification:
Spam
Not Spam
For multi-class classification:
Cat
Dog
Bird
Horse
For regression:
Predicted House Price = $350,000
What Is Forward Propagation?
Forward propagation is the process of moving information from the input layer toward the output layer.
Suppose we have:
Input
↓
Hidden Layer 1
↓
Hidden Layer 2
↓
Output
The input values enter the network.
Each neuron performs calculations using weights and biases.
Activation functions transform those results.
The resulting values are passed to the next layer.
Eventually, the network produces a prediction.
This entire process is called forward propagation or a forward pass.
What Is a Loss Function?
After making a prediction, the network needs to determine how wrong that prediction is.
A loss function measures the difference between the model’s prediction and the desired target.
Suppose the correct house price is:
$400,000
but the neural network predicts:
$350,000
The loss function measures the prediction error.
Different problems use different loss functions.
Common examples include:
- Mean Squared Error
- Binary Cross-Entropy
- Categorical Cross-Entropy
The goal of training is generally to minimize the loss.
Lower loss usually means the model’s predictions fit the training objective better.
What Is Backpropagation?
Backpropagation is one of the key processes used to train neural networks.
After calculating the loss, the network needs to determine how its weights contributed to the error.
Backpropagation works backward through the network:
Output
↑
Hidden Layers
↑
Input Side
Using calculus and the chain rule, it calculates gradients that describe how changing different parameters would affect the loss.
These gradients are then used to update the network’s parameters.
What Is Gradient Descent?
Gradient descent is an optimization technique commonly used to update neural network parameters.
Imagine standing on a mountain and trying to reach the lowest point of a valley.
You repeatedly determine which direction goes downhill and take a step in that direction.
Gradient descent follows a similar idea.
The loss function represents the landscape.
The optimizer attempts to find parameter values that reduce the loss.
A simplified weight update looks like:
New Weight = Old Weight - Learning Rate × Gradient
The learning rate controls the size of each update.
If it is too large, training may become unstable or overshoot useful parameter values.
If it is too small, training may take much longer.
How Does a Neural Network Learn?
Let’s combine everything.
Suppose we are training a neural network to identify cats and dogs.
Step 1: Provide Training Data
We give the model many labeled images.
Image 1 → Cat
Image 2 → Dog
Image 3 → Dog
Image 4 → Cat
Step 2: Forward Propagation
The network processes an image and generates a prediction.
For example:
Prediction: Dog
Correct Answer: Cat
The prediction is wrong.
Step 3: Calculate Loss
The loss function measures how far the prediction is from the desired result.
Step 4: Backpropagation
The model calculates gradients showing how its parameters affected the error.
Step 5: Update Parameters
An optimizer adjusts the weights and biases.
Step 6: Repeat
The process repeats across many examples and training iterations.
Over time, the neural network can learn useful patterns that improve its predictions.
What Is an Epoch?
An epoch means the model has gone through the entire training dataset once.
Suppose your dataset contains:
10,000 images
After the model has processed all 10,000 images once during training, it has completed approximately:
1 Epoch
Training might continue for:
Epoch 1
Epoch 2
Epoch 3
...
Epoch 50
The ideal number of epochs depends on the model, dataset, optimizer, regularization, and other factors.
Training for too few epochs may result in underfitting.
Training for too long without proper controls can contribute to overfitting.
What Is a Batch?
Large datasets are usually not processed all at once.
Instead, data is divided into smaller groups called batches.
For example:
Dataset = 100,000 images

Batch Size = 32
The model processes groups of 32 images at a time and performs parameter updates according to the training setup.
Common batch sizes include:
16
32
64
128
The best batch size depends on factors such as available memory, hardware, model architecture, and training behavior.
Simple Neural Network Example
Consider a neural network that predicts whether a student will pass an exam.
Inputs:
Study Hours = 6
Attendance = 90%
Previous Score = 75%
The network processes these inputs through its learned weights, biases, and activation functions.
It might produce:
Pass Probability = 0.91
Therefore:
Prediction = Pass
During training, the network compares such predictions against actual outcomes and adjusts its parameters accordingly.
Why Do Neural Networks Need Large Amounts of Data?
Neural networks can contain thousands, millions, or even billions of trainable parameters.
Complex models therefore often benefit from large and diverse datasets.
More useful training data can help models learn broader patterns rather than memorizing a small number of examples.
However, more data alone does not guarantee a better model.
Data quality matters enormously.
Training data should ideally be:
- Relevant
- Accurate
- Representative
- Properly prepared
- Diverse enough for the intended task
Poor-quality or biased data can lead to poor or biased predictions.
Types of Neural Networks
Different neural network architectures are designed for different types of problems.
Feedforward Neural Networks
Information primarily moves from the input toward the output.
They can be used for tasks such as classification and regression.
Convolutional Neural Networks
Convolutional Neural Networks (CNNs) are especially well known for computer vision applications.
They can be used for:
- Image classification
- Object detection
- Medical image analysis
- Face-related computer vision tasks
Recurrent Neural Networks
Recurrent Neural Networks (RNNs) were designed to work with sequential information.
They have been used for:
- Time-series data
- Speech
- Text
- Sequence prediction
Variants such as LSTM and GRU were developed to improve learning across longer sequences.
Transformers
Transformers are a neural network architecture that has become especially important in modern AI.
They power many systems involving:
- Large language models
- Generative AI
- Translation
- Text summarization
- Question answering
- Multimodal AI
Modern AI systems often use very large Transformer-based neural networks.
Neural Networks vs Machine Learning
Machine learning is the broader field.
Neural networks are one family of machine learning models.
A simplified relationship is:
Artificial Intelligence
        ↓
Machine Learning
        ↓
Deep Learning
        ↓
Deep Neural Networks
Traditional machine learning includes algorithms such as:
- Linear Regression
- Logistic Regression
- Decision Trees
- Random Forests
- Support Vector Machines
Deep learning primarily relies on neural networks with multiple layers and learned representations.
Real-World Applications of Neural Networks
Neural networks are used across many industries.
Generative AI
Neural networks can generate:
- Text
- Images
- Audio
- Video
- Code
Computer Vision
They can help systems recognize:
- Objects
- Faces
- Vehicles
- Medical imagery
- Documents
Natural Language Processing
Neural networks can help computers process and generate human language.
Applications include:
- Chatbots
- Translation
- Summarization
- Sentiment analysis
- Search
- Question answering
Recommendation Systems
Streaming, shopping, and social platforms can use neural models alongside other techniques to recommend:
- Products
- Videos
- Music
- Posts
- Movies
Healthcare
Neural networks can assist with areas such as medical image analysis and clinical decision-support research.
They should be used with appropriate validation, human oversight, and safety controls in high-stakes settings.
Finance
Potential applications include:
- Fraud detection
- Risk modeling
- Forecasting
- Pattern detection
Advantages of Neural Networks
Neural networks are powerful because they can learn highly complex relationships directly from data.
Major advantages include:
- Ability to model nonlinear relationships
- Automatic feature learning
- Strong performance on images, audio, and language
- Ability to scale to very large datasets and models
- Support for modern generative AI
- Flexibility across classification, regression, and generation tasks
Limitations of Neural Networks
Neural networks also have important limitations.
High Computational Requirements
Large models may require expensive GPUs or other specialized hardware.
Large Data Requirements
Many neural networks perform best with substantial amounts of high-quality training data.
Difficult to Interpret
Complex neural networks can behave like a black box, making individual predictions difficult to fully explain.
Overfitting
A network may perform well on training data but poorly on unseen data.
Techniques such as regularization, dropout, data augmentation, and validation can help.
Training Cost
Training large neural networks can require significant:
- Computing power
- Time
- Memory
- Electricity
- Infrastructure
Neural Networks and Deep Learning
Neural networks are the foundation of deep learning.
The word “deep” generally refers to using multiple layers of learned transformations.
A basic network could have only a small number of layers.
A modern deep learning model may contain many layers and a huge number of parameters.
As models become deeper and larger, they can learn increasingly sophisticated representations, although scale also introduces greater computational and engineering challenges.
Do Neural Networks Work Like the Human Brain?
Neural networks were partly inspired by ideas about biological neurons, but artificial neural networks are not digital copies of the human brain.
Artificial neurons are mathematical operations.
A typical artificial neuron calculates something like:
Inputs
   ↓
Weights
   ↓
Weighted Sum + Bias
   ↓
Activation Function
   ↓
Output
The human brain is vastly more biologically complex.
Therefore, the term neural network should be understood as an inspiration and mathematical modeling concept rather than an exact simulation of human intelligence.
Simple Neural Network Workflow
Here is the complete process in simplified form:
Collect Data
     ↓
Prepare Data
     ↓
Initialize Neural Network
     ↓
Forward Propagation
     ↓
Generate Prediction
     ↓
Calculate Loss
     ↓
Backpropagation
     ↓
Update Weights and Biases
     ↓
Repeat Training
     ↓
Evaluate Model
     ↓
Use Model on New Data
This repeated learning process allows neural networks to gradually improve at a specific task.
Frequently Asked Questions
How does a neural network work in simple terms?
A neural network receives numerical input, processes it through interconnected layers using weights, biases, and activation functions, and generates an output. During training, it compares predictions with target answers and adjusts its parameters to reduce future errors.
What are weights in neural networks?
Weights are trainable parameters that control the influence one neuron or feature has on another.
What is bias in a neural network?
Bias is an additional trainable parameter that helps neurons shift their output and learn more flexible relationships.
What is backpropagation?
Backpropagation is the process of calculating gradients through the network so the model can determine how its parameters should change to reduce the loss.
What is an activation function?
An activation function transforms a neuron’s calculated value. Nonlinear activation functions allow neural networks to learn complex patterns.
Are neural networks AI?
Neural networks are a major technology used within artificial intelligence and machine learning. They are not synonymous with all AI.
Is ChatGPT based on neural networks?
Yes. ChatGPT is built using neural-network technology, including the Transformer architecture.
Final Thoughts
Neural networks are a core technology behind modern artificial intelligence.
At their heart, they follow a surprisingly understandable process:
Receive data → perform weighted calculations → make a prediction → measure the error → adjust parameters → repeat.
Individual calculations can be simple, but combining huge numbers of neurons, parameters, training examples, and layers allows neural networks to learn remarkably complex patterns.
Understanding concepts such as neurons, layers, weights, biases, activation functions, forward propagation, loss functions, backpropagation, and gradient descent gives you a strong foundation for learning deep learning and modern AI.
Once these fundamentals are clear, the next step is to learn how to build and train a simple neural network yourself using tools such as Python, NumPy, Scikit-learn, TensorFlow, or PyTorch.